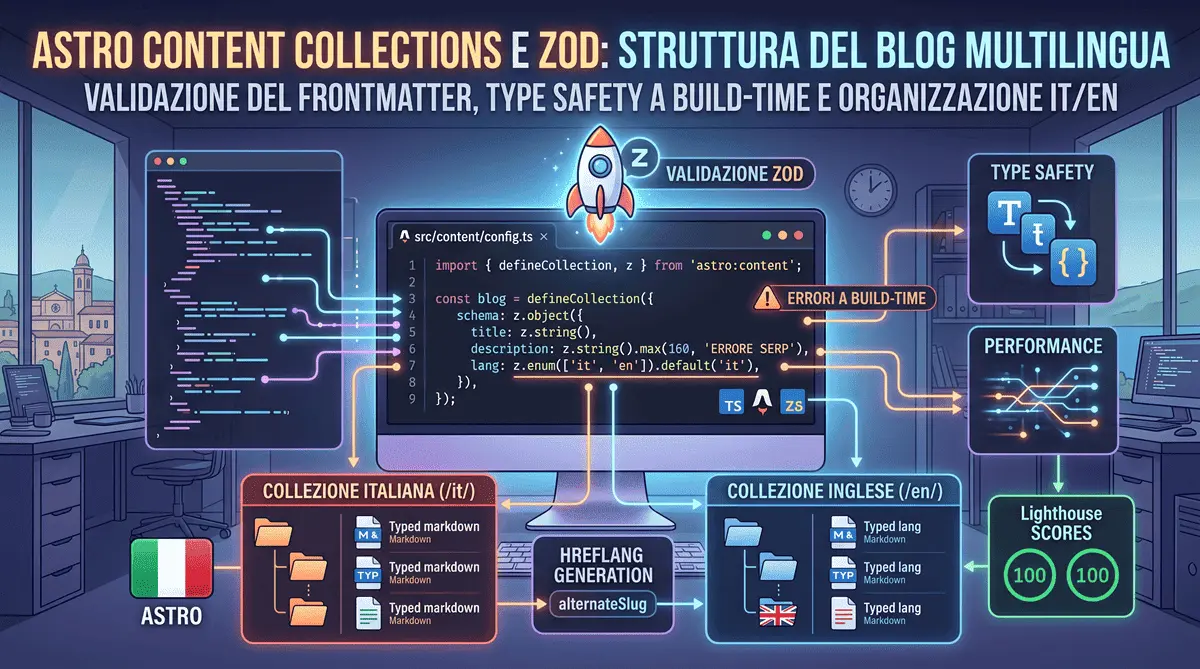
Astro Content Collections and Zod: How I Structured This Multilingual Blog
If you are reading this article and browsing the sections of my site, you are using one of Astro’s most interesting features: Content Collections. Every article you see is a Markdown file, and between that file and the page there is a validation layer that decides what is allowed online.
Until a few years ago, managing a Markdown-based blog meant discovering errors only in production. A misspelled field in the frontmatter, a missing date, or an overly long description slipped through silently and ended up on the pages. With Content Collections, Astro validates every file against a Zod schema at build time, and if something is wrong the build stops with a precise message.
Here is how the blog you are reading is actually organized, with the project’s real code and its honest limits.
The Real Schema: The Content “Customs Checkpoint”
The schema lives in src/content/config.ts. This is the complete file, with no simplifications:
// --- IMPORTS ---
import { defineCollection, z } from 'astro:content';

// --- BLOG COLLECTION DEFINITION ---
const blog = defineCollection({
    type: 'content',
    // --- SCHEMA DEFINITION WITH ZOD ---
    schema: z.object({
        title: z.string(),
        description: z.string().max(160, 'La meta description dovrebbe restare entro i 160 caratteri per evitare troncamenti in SERP.'),
        cardDescription: z.string().max(115, 'La card description deve restare corta per evitare troncamenti su mobile (line-clamp-3).'),
        pubDate: z.coerce.date(),
        updatedDate: z.coerce.date().optional(),
        heroImage: z.string().optional(),
        imageAlt: z.string().optional(),
        imageTitle: z.string().optional(),
        imageCaption: z.string().optional(),
        tags: z.array(z.string()).optional(),
        lang: z.enum(['it', 'en']).default('it'),
        alternateSlug: z.string().optional(),
        faqs: z.array(
            z.object({
                question: z.string(),
                answer: z.string(),
            })
        ).optional(),
    }),
});

// --- EXPORT COLLECTIONS ---
export const collections = { blog };
A few things about this schema matter, because they separate what the system enforces from what I merely intend:
- Only two limits actually block the build:
description(at most 160 characters, the point where Google truncates the SERP snippet) andcardDescription(at most 115, for cards on mobile). This is not theory: while building this blog, acardDescriptionlonger than the limit made the dev server fail with anInvalidContentEntryDataError, exactly as designed. The error names the file and the field, so the fix takes seconds. - The title has no length limit. I didn’t impose one: a longer title breaks nothing technical, so a length rule there would be an editorial choice, not a system constraint.
- The hero image is optional. A missing
heroImagedoes not block the build: the article still publishes, and the layout handles the absence of an image. - Tags are plain strings.
tags: z.array(z.string())accepts any value: the schema does not check that a tag exists in the official registry. The controlled vocabulary lives insrc/data/tags.tsand is used for human-readable labels, falling back to the raw key when a tag isn’t registered. I state this limit openly: a typo in a tag doesn’t break the build, it only shows up on the page. Constraining tags with az.enumbuilt from the registry would be the natural next step.
Multi-Language Organization: One Collection, Two Languages
Instead of splitting collections by language, I use a single blog collection with files divided into two folders:
src/content/blog/
├── it/
│   ├── astro-content-collections-zod-blog-multilingua.md
│   └── sicurezza-siti-web-csp-astro-marche.md
└── en/
    ├── astro-content-collections-zod-multilingual-blog.md
    └── website-security-csp-astro-guide-italy.md
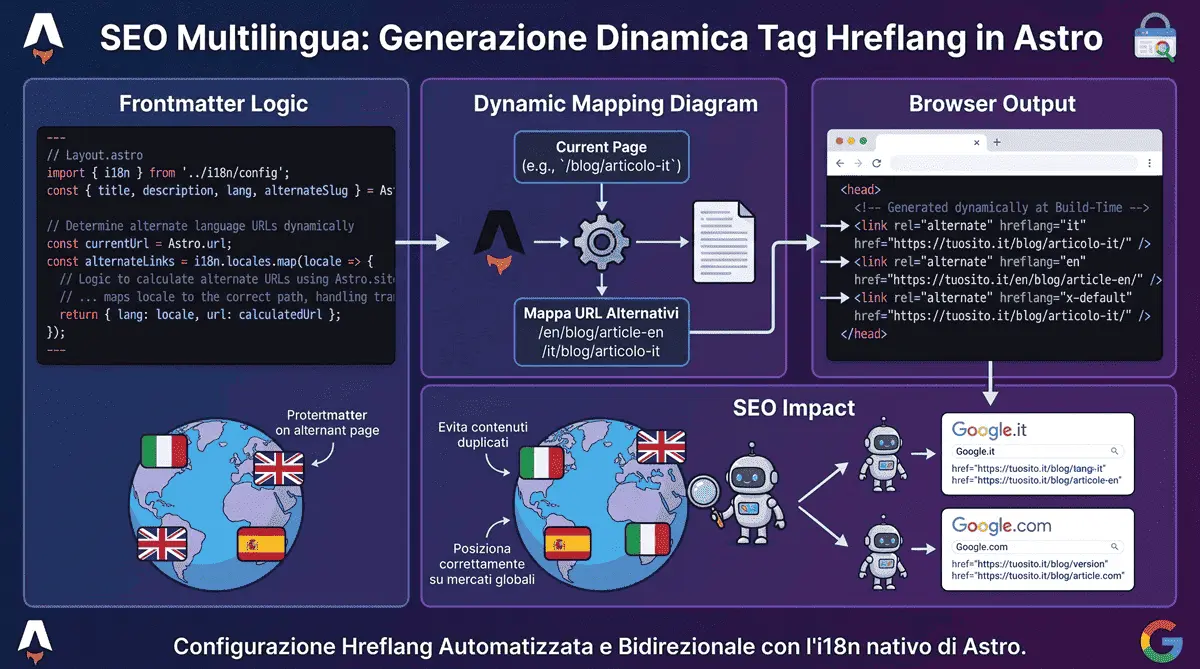
An article’s language is determined not by its folder but by the lang field in the frontmatter, validated by the schema as 'it' or 'en', with 'it' as the default. The link between the two versions of the same article is the alternateSlug field: each article declares the slug of its translation, and the shared layout uses it to generate the hreflang tags and the language switcher in the header. I explain this mechanism in detail in my article on hreflang and multilingual SEO.
A practical detail you’ll run into immediately: Astro’s generated slug includes the folder, so it becomes it/article-name. That’s why the real code always contains a line like post.slug.replace(/^it\//, '') before building a link.
Querying the Collection
The real code of the page listing the Italian articles (src/pages/blog/index.astro) filters by language and sorts by descending date:
const posts = (await getCollection('blog', ({ data }) => data.lang === 'it')).sort(
    (a: CollectionEntry<'blog'>, b: CollectionEntry<'blog'>) => b.data.pubDate.valueOf() - a.data.pubDate.valueOf()
);
The same filtering pattern feeds the three latest articles on the homepage (LatestPosts.astro, with .slice(0, 3)) and the related articles at the bottom of every post (RelatedPosts.astro). The advantage is that selection logic lives in one place and the fields are typed: TypeScript knows pubDate is a Date because the schema declares it with z.coerce.date().
What Building It Taught Me
A blog like this is not “just text online”. Build-time validation surfaces errors before publication, the language filter keeps the two versions separate yet linked, and the SEO length limits are enforced by the system instead of left to memory. The most useful thing to remember, though, is what the schema does not check, such as tags: validation is only as trustworthy as its coverage, and knowing where it stops is part of the job.
If you want to see how these choices connect to the rest of the site, start with the XML sitemap and robots.txt guide: the sitemap reads each article’s updatedDate from the frontmatter to compute its lastmod.
Frequently Asked Questions
What are Astro Content Collections and what are they used for?
Content Collections are a built-in Astro feature for organizing, querying, and strongly typing local content, such as Markdown files. They replace the older Astro.glob() approach with a more robust API that integrates with TypeScript.
Why validate Markdown frontmatter with Zod in Astro?
Zod checks the frontmatter of every file at build time: if an article breaks a limit or has a wrong field, Astro stops the build and reports the exact error. On this blog, for example, a cardDescription longer than 115 characters cannot reach production with truncated text in the cards.
Do you build custom Astro blogs and architectures for international businesses?
Yes. Operating from Civitanova Marche, Italy, I build Astro web platforms for global clients, from native multi-language routing to typed content collections, delivering scalable systems with no technical debt in the content layer.
Have a similar project in mind?
If this article gave you useful ideas, I can help you put them into practice on your site or project.
Get a Free Quote