XML Sitemap and Robots.txt: The Guide I Wish I Had Read at the Beginning
When we launch a new website, we often spend hours perfecting CSS animations, optimizing images, and refining the copy. Then, we publish the site and forget about two tiny text files that dictate how Google will interact with our work: robots.txt and sitemap.xml.
Early in my career, I used to configure these files mostly by inertia, copying and pasting from old projects. It’s a mistake many developers make. Understanding exactly how they work is not just a “nice to have,” but the absolute foundation of Technical SEO - the same principle behind every choice I cover in my 2026 Core Web Vitals guide.
Here is the practical, no-nonsense guide I wish I had read years ago.
1. Robots.txt: The Site’s Bouncer
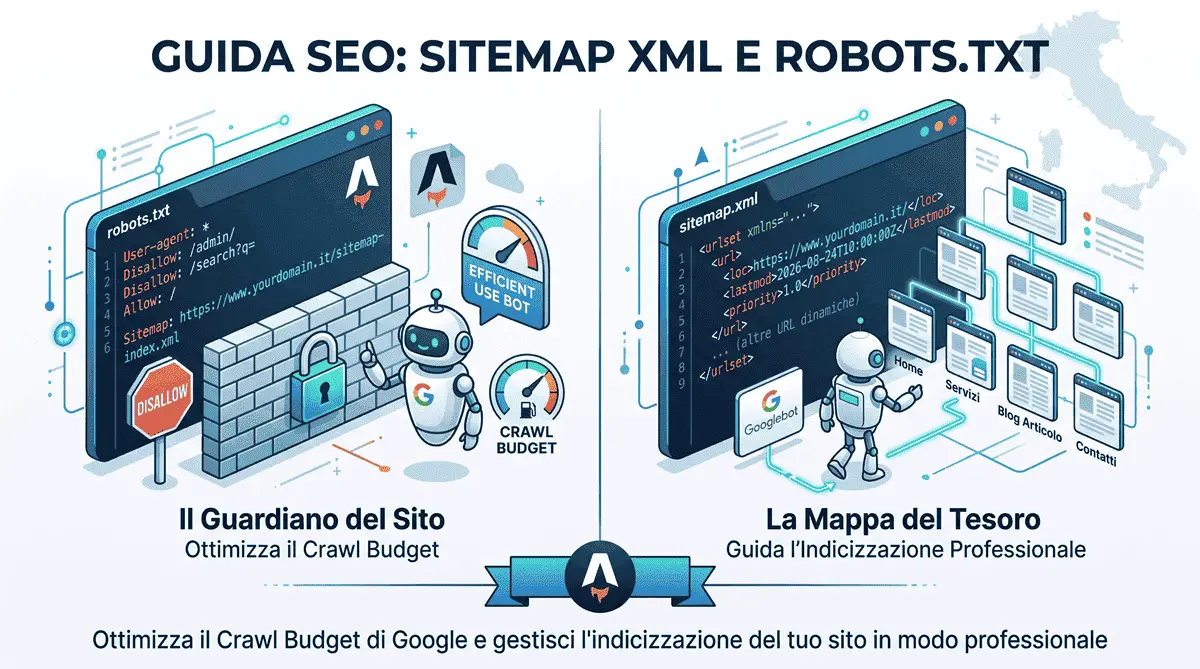
The robots.txt file is always located in the root directory of your site (yoursite.com/robots.txt). It is the first thing crawlers (like Googlebot) look at when they arrive. Its instructions tell the bots which rooms in your house they can visit and which doors must remain closed.
Basic Syntax
Directives work via two main commands: User-agent (which bot you are addressing) and Disallow (what they cannot crawl).
User-agent: *
Disallow: /admin/
Disallow: /search?q=
Allow: /
In the script above, we are telling all bots (*) not to crawl the administration folder and not to crawl internal search result pages (to avoid wasting Crawl Budget on low-value pages).
The Deadly Mistake
The biggest SEO disaster you can make is accidentally leaving this line when moving the site from staging to production:
User-agent: *
Disallow: /
This command tells Google: “Go away, don’t look at any pages on my site”. Your site will literally vanish from search engines in a matter of days.
2. XML Sitemap: The Treasure Map
If robots.txt tells bots where not to go, the sitemap.xml is the map that suggests where they absolutely should go. It is a list of all the URLs on your site that you want to see appear on Google. Once it’s ready, the right place to manually submit it to Google (and monitor any crawl errors) is Google Search Console - I cover this in detail in my practical Search Console guide.
What to include (and what NOT to include) in the Sitemap
One of the most common mistakes is using plugins or scripts that dump every page of the site into the sitemap. This is very wrong. Your sitemap must only contain canonical, indexable URLs that return a 200 (OK) status code.
Never include:
- Pages with a
noindextag (e.g., the “Thank you for contacting us” page). - Pagination pages (e.g.,
/blog/page-2). - URLs returning 404 errors or redirecting elsewhere (301).
Including “garbage” in the sitemap causes Googlebot to lose trust in the quality of your map.
A Myth Worth Downsizing: priority and changefreq
In the past, XML files included values like <priority>0.8</priority> and <changefreq>weekly</changefreq>. An important tip: today, Google openly states it ignores these two fields, relying on its own algorithms to figure out how often you update a page. The only attribute Google still looks at with real interest is <lastmod> (the last modified date) - provided it’s accurate and not artificially bumped on every build.
That said, on this very site I still set priority and changefreq per page type (the homepage at 1.0/weekly, the services page at 0.9/monthly, individual blog posts at 0.6/monthly, tag pages at 0.3). Not for Google’s benefit - it costs nothing to maintain, it doubles as internal documentation of the site’s priorities, and a handful of other engines or SEO monitoring tools may still take it into account. The lastmod, on the other hand, is calculated dynamically from each article’s real update date - that’s the one Google genuinely weighs.
The Missing Link
There is a golden rule that many ignore: you must always declare your sitemap link at the end of your robots.txt. It is the fastest way for search engines to find it. This is, verbatim, the robots.txt running in production on this site:
User-agent: *
Allow: /

Sitemap: https://www.leonardocastignani.it/sitemap-index.xml
How I Handle It in Astro
In traditional frameworks, creating a dynamic sitemap can be tedious. With Astro, the process is automated through the official @astrojs/sitemap integration, configured in astro.config.mjs. One important clarification, since it’s a common misconception: the integration does not automatically inject the link into robots.txt - that file stays static, and the link needs to be declared by hand, once, as in the example above.
What the integration actually does is generate the sitemap on every build by reading all existing routes and applying the rules I pass it. This is, simplified, the core of this site’s real configuration:
// astro.config.mjs
sitemap({
  // Excludes noindex-tagged tag pages from the sitemap (in this case "updates")
  filter: (page) => !/\/blog\/tag\/aggiornamenti\/?/.test(new URL(page).pathname),
  serialize(item) {
    const { pathname } = new URL(item.url);
    // Assigns different priority/changefreq per page type,
    // and pulls each article's real lastmod from its frontmatter
    return { ...item, ...getSitemapOverrides(pathname) };
  }
})
In practice: the homepage gets maximum priority and a weekly cadence, tag pages (low SEO value) drop to 0.3, and every blog post gets its real lastmod, calculated from the updatedDate declared in each post’s frontmatter - not a fake date regenerated on every deploy, a detail that makes a real difference to the sitemap’s credibility in Google’s eyes.
Conclusion
Your code might be pristine, but if you don’t give Google the correct directions to navigate it, your organic traffic will suffer. Intentionally (and not casually) configuring your robots.txt and sitemap.xml means having full control over how the world discovers your project - the same care I put into JSON-LD structured data to make every page not just crawlable, but genuinely understandable to search engines.
Frequently Asked Questions
What is the difference between sitemap.xml and robots.txt?
The robots.txt file acts as a 'bouncer,' telling Googlebot's crawlers which directories or pages they are forbidden to scan. The sitemap.xml, on the other hand, is a map that actively points search engines to the most important pages you want indexed. They're complementary: one filters, the other guides.
What should you never include in an XML Sitemap?
You should never include non-canonical pages, URLs with a 'noindex' tag, pagination pages, or links that result in 404 errors or 301 redirects. On this very site, for instance, I exclude noindex-tagged tag pages from the sitemap through a simple filter in the Astro configuration.
Do you offer Technical SEO audits for international businesses?
Yes, I provide comprehensive Technical SEO services for international clients and local businesses. Based in Civitanova Marche, Italy, I engineer high-performance websites optimizing everything from Crawl Budgets and dynamic Sitemaps to advanced JSON-LD structured data architectures.
Have a similar project in mind?
If this article gave you useful ideas, I can help you put them into practice on your site or project.
Get a Free Quote